Selected
SnapLine
Business Challenge
The Problem That Needed Solving.
In commercial and specialty insurance, every submission arrives as a bundle of unstructured documents—a broker email, a schedule of values in Excel, loss runs as scanned PDFs, an MRC slip, and ACORD forms. Before anyone can underwrite, a person has to read all of it, find the fields that matter, and re-key them into downstream systems. That costs hours per risk, and the errors are expensive: a missed sprinkler declaration or a mis-keyed total insured value flows straight into pricing. The questions that actually drive the decision—what hazards surround this location, whether the declared value is credible, and whether the building is occupied—are usually not answered anywhere in the submission.
Resolving
How We Approached It.
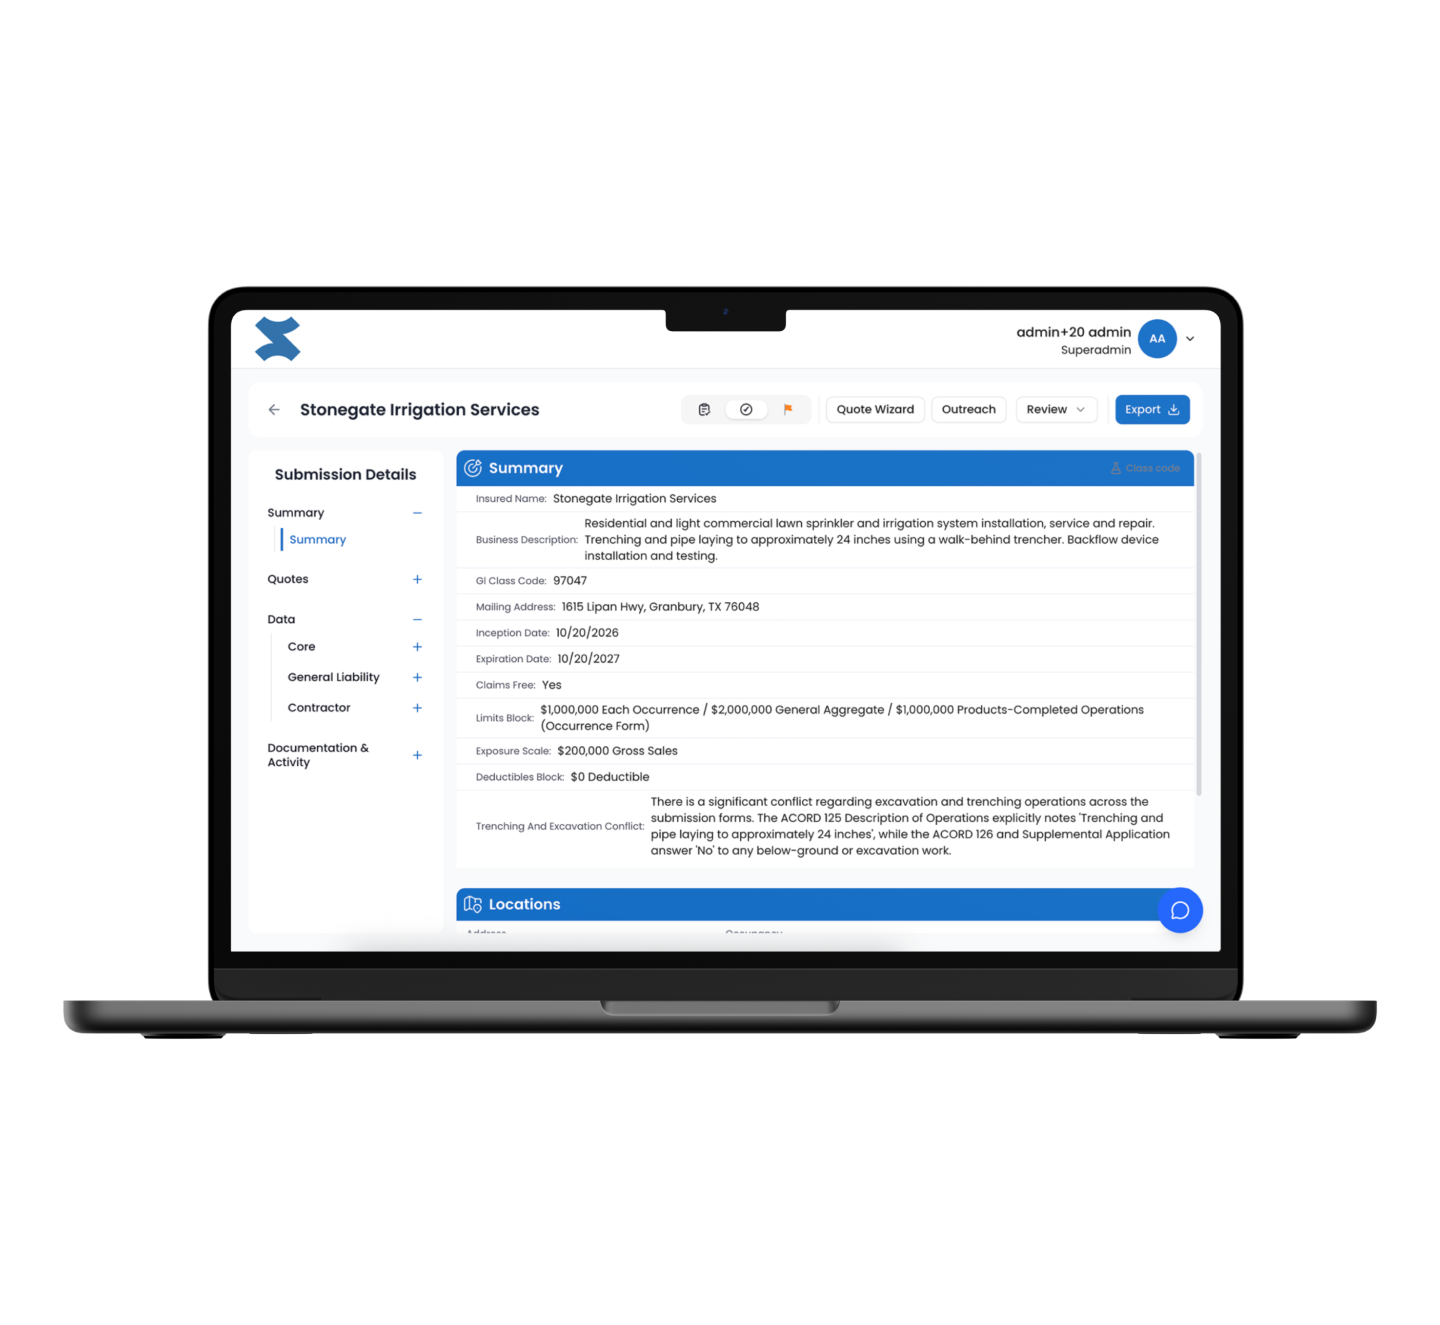
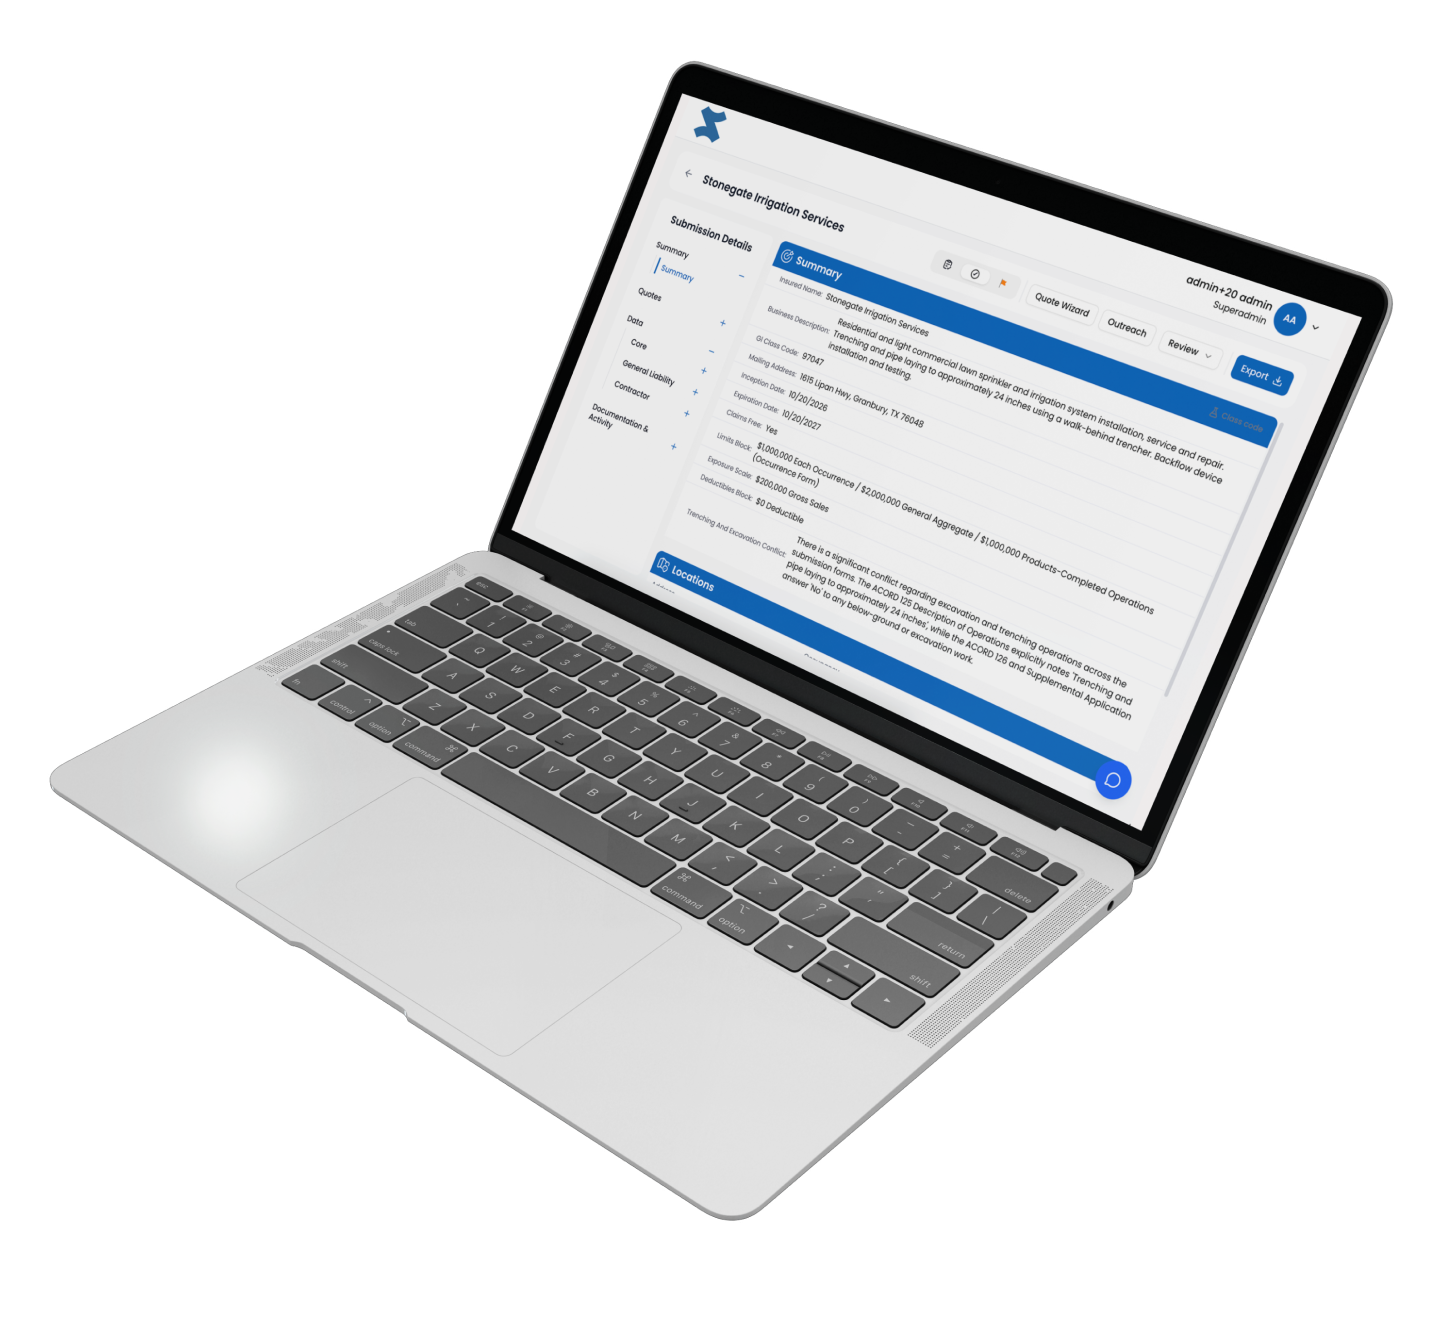
We built SnapLine as a single pipeline from broker inbox to underwriter screen. Submissions land by email, Outlook add-in, or upload in any format, with no manual pre-processing. An event-driven pipeline of specialized AI agents classifies each document, extracts every underwriting-relevant field in parallel, validates it with data-quality, mandatory-field, and total-insured-value checks plus appetite and sanctions screening, and produces one structured record per risk with per-field provenance back to the source document. Atlas adds per-location hazard profiles, rebuild-cost benchmarks, and vacancy detection from more than 50 data sources. Extraction is configuration rather than code, and one deployment serves every carrier through SnapLine's underwriter interface or headlessly through existing systems.
Technologies Used
The Stack.
A hub-and-spoke system: a Go core API for the data model, JWT authentication with per-organization MFA, multi-tenancy, Microsoft Graph email ingestion, and the headless API. A React and TypeScript underwriter app acts as a thin client, while a fully decoupled serverless Python agent pipeline runs on AWS Lambda with a multi-provider LLM layer spanning Gemini, OpenAI, and Bedrock with automatic fallback. PostgreSQL runs on RDS, services deploy to ECS Fargate, and Terraform manages the multi-account AWS estate with the encryption, logging, threat-detection, and backup controls that underpin ISO 27001 and SOC 2.


Development Process
How We Worked Together.
Our team built and operates the platform end to end, with infrastructure treated as product code from day one. Key milestones: Go core API and serverless extraction pipeline → underwriter web app, chat assistant, and Outlook add-in → configuration-driven extraction maintained by business users → multi-tenant onboarding with per-submission configuration selection → Atlas risk-intelligence enrichment → headless API and dedicated per-carrier AWS environments → ISO/IEC 27001, ISO/IEC 42001, and SOC 2 Type II hardening.
Measurable Results
What Actually Changed.
What changed after launch—measured across submission-handling time, onboarding speed, and data quality reaching the underwriter. Live in production with Lloyd's syndicates and specialty MGAs; Lloyd's Lab Cohort 15 finalist.
To process a submission that previously took hours of reading and re-keying
From client sign-up to the first processed submission
Integrations required to start and zero manual data entry after go-live
Of extracted fields traceable to their source document
Data sources enriching every location with risk intelligence
Measurable Results
Final Product